The Energy Cost of Spoken Replies in Omni-Modal Models
Under review at DAC 2027
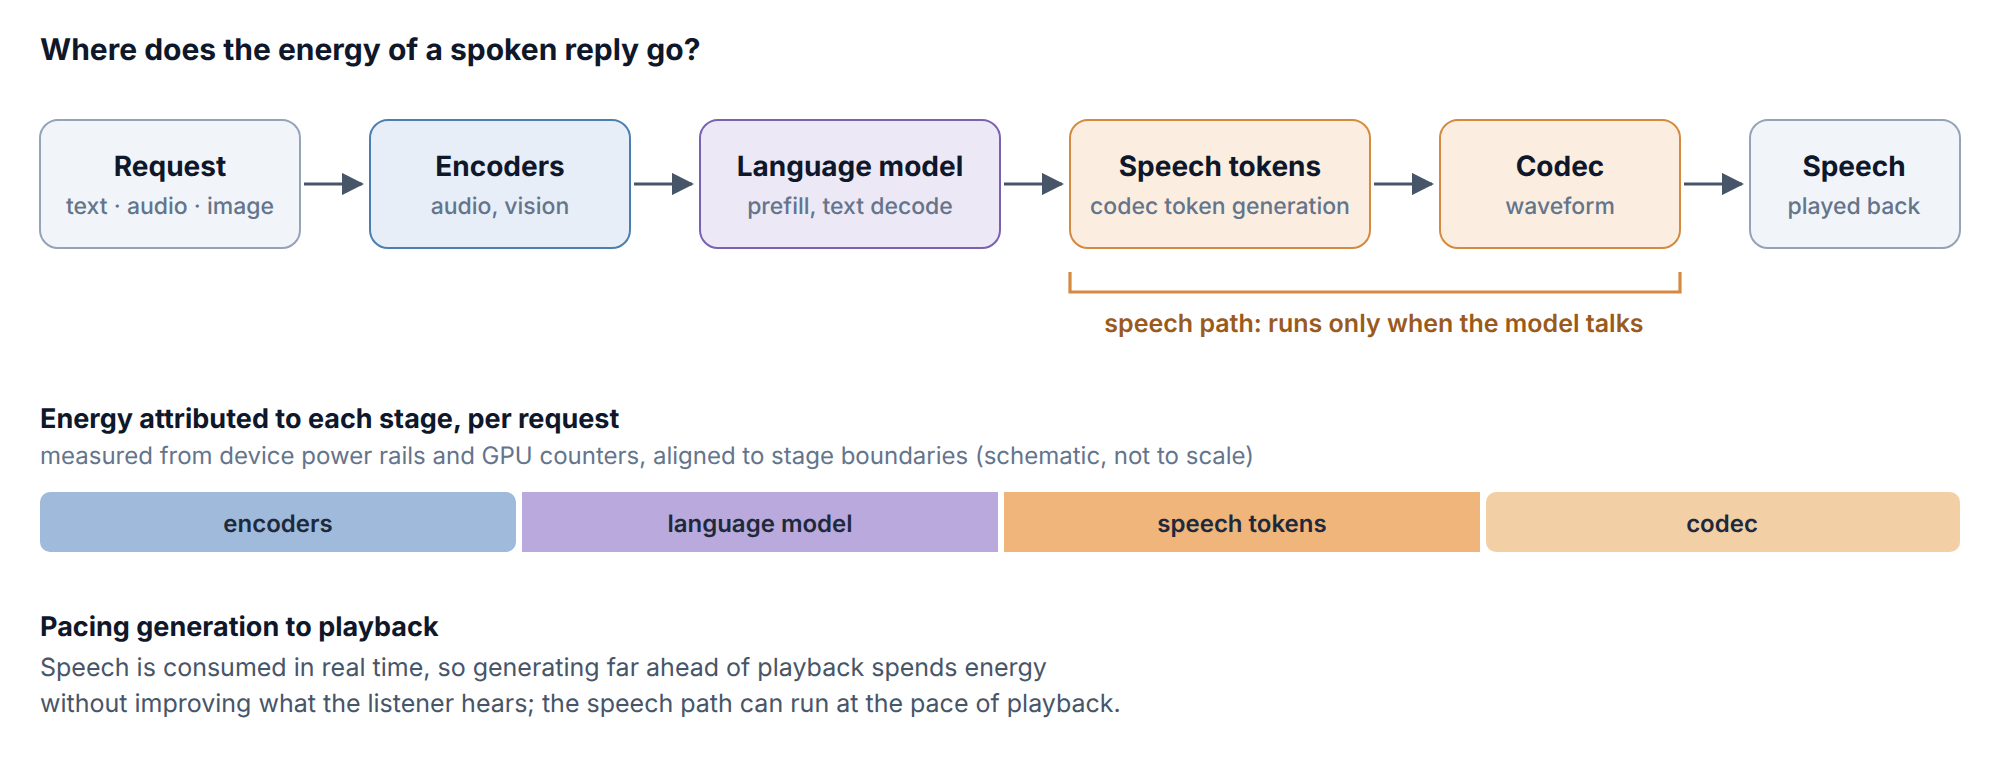
Omni-modal models can answer in speech as well as text, but a spoken reply runs additional generators after the language model: a speech-token generator and a codec that produces the waveform. How much energy this speech path costs, and where it is spent, has not been measured systematically.
This project attributes the energy of each request to its stages (encoders, language model, speech-token generation and codec) across models, input modalities and hardware, and studies how to reduce the speech path’s cost, for example by pacing generation to the rate at which speech is played back rather than generating far ahead of the listener.
Details will be shared after the review process.